

 ENG
- KI-Beschleunigung
- Branchen
- Finanzen
Nearshore-Softwareentwicklung für den Finanzsektor – sicher, skalierbar und Compliance-gerechte Lösungen für Banking, Zahlungsverkehr und APIs.
- Einzelhandel
Softwareentwicklung für den Einzelhandel – E-Commerce, Kassensysteme, Logistik und KI-gestützte Personalisierung durch unsere Nearshore-Engineering-Teams.
- Verarbeitende Industrie
Nearshore-Softwareentwicklung für die Industrie – ERP-Systeme, IoT-Plattformen und Automatisierungstools zur Optimierung industrieller Abläufe.
- Finanzen
- Was wir tun
- Dienstleistungen
- Technologien
- Collaboration models
- Kooperationsmodelle
Kooperationsmodelle passend zu Ihren Bedürfnissen: Komplette Nearshoring Teams, deutschsprachige Experten vor Ort mit Nearshoring-Teams oder gemischte Teams mit unseren Partnern.
- Arbeitsweise
Durch enge Zusammenarbeit mit Ihrem Unternehmen schaffen wir maßgeschneiderte Lösungen, die auf Ihre Anforderungen abgestimmt sind und zu nachhaltigen Ergebnissen führen.
- Kooperationsmodelle
- Über uns
- Wer wir sind
Wir sind ein Full-Service Nearshoring-Anbieter für digitale Softwareprodukte, ein perfekter Partner mit deutschsprachigen Experten vor Ort, Ihre Business-Anforderungen stets im Blick
- Unser Team
Das ProductDock Team ist mit modernen Technologien und Tools vertraut und setzt seit 15 Jahren zusammen mit namhaften Firmen erfolgreiche Projekte um.
- Wozu Nearshoring
Wir kombinieren Nearshore- und Fachwissen vor Ort, um Sie während Ihrer gesamten digitalen Produktreise optimal zu unterstützen. Lassen Sie uns Ihr Business gemeinsam auf das nächste digitale Level anheben.
- Wer wir sind
- Unser Leistungen
- Karriere
- Arbeiten bei ProductDock
Unser Fokus liegt auf der Förderung von Teamarbeit, Kreativität und Empowerment innerhalb unseres Teams von über 120 talentierten Tech-Experten.
- Offene Stellen
Begeistert es dich, an spannenden Projekten mitzuwirken und zu sehen, wie dein Einsatz zu erfolgreichen Ergebnissen führt? Dann bist du bei uns richtig.
- Info Guide für Kandidaten
Wie suchen wir unsere Crew-Mitglieder aus? Wir sehen dich als Teil unserer Crew und erklären gerne unseren Auswahlprozess.
- Praktikum im Anfänger-Bootcamp
Starte deine IT-Karriere mit dem Rookie Boot Camp, unserem bezahlten Praktikumsprogramm, in dem Studenten und Absolventen Fähigkeiten aufbauen, Selbstvertrauen gewinnen und praktische Erfahrungen sammeln.
- Arbeiten bei ProductDock
- Newsroom
- News
Folgen Sie unseren neuesten Updates und Veröffentlichungen, damit Sie stets über die aktuellsten Entwicklungen von ProductDock informiert sind.
- Events
Vertiefen Sie Ihr Wissen, indem Sie sich mit Gleichgesinnten vernetzen und an unseren nächsten Veranstaltungen Erfahrungen mit Experten austauschen.
- News
- Blog
- Kontakt
17. Sep. 2026 •5 minutes read
Can AI help you revive a project nobody has touched in years?
Bruno Raljić
Unit Lead & Integrations Service Lead at ProductDock
This post is the first in a series about reviving a project that had sat untouched for years. Each post will explore a different aspect of the process, some technical, others focused on how we interpreted and acted on our findings. This article starts at the very beginning, before anyone had looked at a single line of code. Follow the series for the rest of the story.
Every engineering org has one of those projects that hasn’t been touched in years, and that everyone is a little afraid to go near. The problem isn’t bad code; it’s that nobody currently on the payroll fully understands what’s inside it, and finding out the hard way tends to happen at the worst possible time.
For this post, we picked a project that fits that story well: not business-critical, but complex enough to make the point. Originally built as an internal side project to test new technologies, the fantasy football simulator ended up being a genuinely used tool, with colleagues repeatedly returning to see how the simulated matches played out.
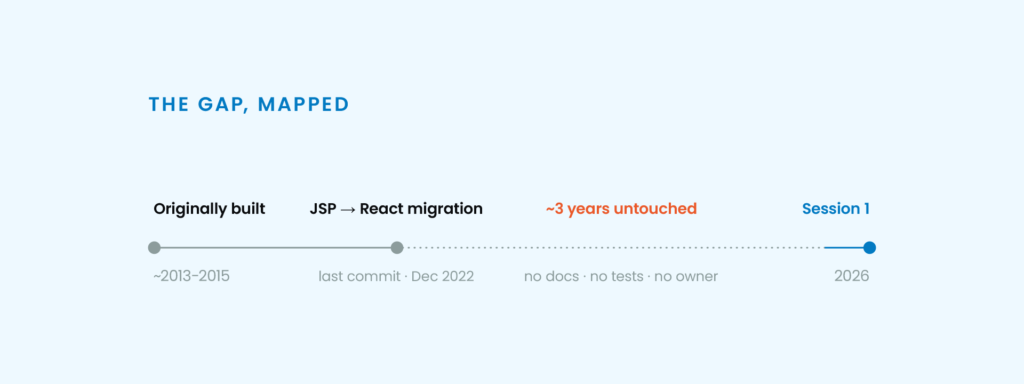
It was abandoned, picked up again in 2022 for a modernization pass, then abandoned a second time. As a fun, internal side project, not something built the way we’d normally build for a client, it had no docs and no tests worth trusting, a black box with a git history that only went back so far: the repo had been moved at some point, and nobody bothered preserving what came before.
What we did
Before opening a single file, the project’s original owner was asked to write down everything they could remember about it, cold, with no peeking at code, down to the smallest detail. What we received went into a real file, one that would actually get used later, not a throwaway exercise. Neither side had a head start: the owner never looked at the code while writing it, and the AI never looked at that file until it was time to compare the two.
Then, we let an AI-assisted team do a full pass on all repos, one session, no code touched:
- Git history
- Stack versions
- Dependency health
- Test coverage
- A scan for committed secrets
- A sweep for dead code and half-finished features
The goal wasn’t just to be fast. It was to see how far a human memory, even an honest, well-intentioned one, genuinely drifts from what’s true after a few years away. And then to build a real, current picture fast enough that “we don’t know what’s in there” stops being an excuse not to touch it.
One technical moment
Buried in the backend was a Java class called Todo.java, whose entire body was comments, fifteen TODO items that never became tickets, plus a leftover MongoDB query and a Windows build path from someone’s old dev machine. One of those comments carried a literal timestamp: ISODate("2014-02-13...").
The project’s creator recalls it being written sometime between 2013 and 2015, though the exact timeframe remains uncertain. A single fossilized comment, never meant to prove anything to anyone, pinned that down to a specific week. That’s the kind of detail you can’t get from a changelog, because there wasn’t one. It survived only by accident, sitting inside a class that probably shouldn’t have existed at all, a running backlog kept as comments in a Java file instead of real tickets, for whatever reason, the developer at the time found that convenient. We don’t know why. We just know nobody had looked at that class in over a decade.
Where AI helped
The reconstruction itself held up well against memory almost everywhere: the match-simulation engine, the betting subsystem, the weather feature that was wired in but never actually affected outcomes, even a “secret” admin endpoint for generating a new season, all confirmed, independently, from the code.
Where it mattered was a smaller, quieter mismatch. The original owner’s memory said the 2022 migration to React was “done.” The reconstruction found it was only partially done: the core engine was ported cleanly, but several pages (Wall of Fame, the betting UI) were still living only as JSP and never finished. Both things were technically true: the instruction at the time was “make it functionally work,” and it did, for the parts that were touched. Nobody had ever written down what “done” was supposed to mean, so two accurate memories of the same project quietly disagreed with each other. Catching that gap and deciding what to do about it needed a human in the loop. An AI reconstruction can tell you what’s there; it can’t tell you which version of “done” the person asking really meant.
That first session pass also ended with a blunt verdict: would we deploy this today? No, for eight concrete reasons:
- Committed OAuth2 secrets and a JWT signing key, sitting in the repo
- Admin endpoints that delete data are reachable with a plain, unauthenticated GET request
- A JWT library with a known algorithm-confusion vulnerability
- A logging library still pinned to a 2006 release, already outdated the day the project was built
- Security configuration built on an API that’s deprecated now, blocking any further upgrade
- A push-notification integration pointing at a service that’s been shut down for years
- A season-generation job that was never finished: it would run once, then stop forever
- Near-zero test coverage on the backend, and none at all on the frontend
All discoverable in one sitting. None of them was a surprise once someone actually looked.
Why this matters if you’re hiring a nearshoring team
This is precisely the kind of challenge a nearshoring team is built for: stepping into a codebase nobody on your side has the time to relearn, and getting it back under control.
What AI changes here isn’t just the pace; it’s what becomes worth taking on in the first place. A frozen, undocumented project like this used to be a hard sell: too much unknown risk for too little certainty going in. A single session that turns “we don’t know what’s in there” into an eight-item list changes that math. Getting oriented to an unfamiliar codebase typically takes up the first few weeks of a new hire’s onboarding (industry average, not a pessimistic number). Here, it took one sitting.
Speed alone isn’t the real selling point; after all, anyone with an AI subscription has access to that now. It’s judgment applied at that speed: knowing which of the eight things above needs fixing first, which can wait, and which shouldn’t be touched without a real conversation first.
None of that made the project any less abandoned. It just changed what “abandoned” meant: no longer a mystery, but a list. That’s a small difference on paper, and the actual difference between a project nobody will touch and a project someone can actually start on. This is just the beginning of that list.
What’s next
The posts that follow cover what real documentation and understanding looked like once we actually opened the code, what a proper security and technical-debt review turned up, what it actually felt like to go from zero test coverage to feeling confident enough to ship a real new feature (compare that to handing an intern a feature request on a codebase nobody can even say is covered), and an honest audit of our own work, including the calls we made about what not to fix. Somewhere in that mix is also a real dead end for AI: not a case where it needed a human to decide, but one where it simply had no answer, no matter how the question was asked.
Stay tuned for the rest of the series to see how we nurture the human-in-the-loop principle at ProductDock and why it has brought results.
Tags:Skip tags
Bruno Raljić
Unit Lead & Integrations Service Lead at ProductDockBruno has been in software since 2011, starting as a developer and growing into a role that sits between people, clients, and delivery. At ProductDock, he builds and leads teams, works directly with clients, and focuses on the human side of software projects. He believes that in the age of AI, the people on a project matter more than ever, not less.
Related posts.
KI
Elasticsearch deep dive: From distributed search to the full power of the ELK stack
Nemanja Marić• 10. Sep. 2026
Find out more
Allgemein, Backend, Integration, KI
I let an AI agent call my REST API: Here’s what I had to fix
Danijel Dragičević• 03. Sep. 2026
Find out more
Digital solutions, KI, Produkt
Ask anything, share nothing: How we built our AI assistant for internal documents
Jovica Zorić• 31. Juli 2026
Find out more